A database of 50,000 contacts with 2% invalid addresses means 1,000 messages coming back as hard bounces on every campaign. The CRM still shows 50,000 rows. Data quality lives in the gap between what the database holds and what you can actually do with it. It is the degree to which a dataset fits its intended use. Six criteria measure it: accuracy, completeness, validity, consistency, timeliness and uniqueness, each with a figure you can track, detailed below.
What data quality means
Data quality is the degree to which a dataset suits the use you plan to make of it. A piece of data is not good or bad in itself: a landline number is fine for a billing department and useless for an SMS campaign. This idea of fitness for purpose is why two teams in the same company judge the same customer table differently.
Two notions that glossaries tend to blur need separating. Data governance sets who owns which data and under which rules; quality measures what those rules produce in practice. A company can have a flawless governance charter and 15% duplicates in its CRM.
The six criteria, from accuracy to uniqueness
Frameworks differ from one vendor to the next: some list fewer criteria, others more (integrity, compliance, plausibility). These six are the most common. The “availability” criterion you often see cited is about access and architecture, not about the content of the data.
| Criterion | Question asked | Measurable indicator | Example on an email |
|---|---|---|---|
| Accuracy | Does the value reflect reality? | Error rate on a controlled sample | The address exists, but the name attached to it belongs to another contact |
| Completeness | Are the required fields filled in? | Completeness rate per field | Contact with no email and no phone number |
| Validity | Does the format follow the rule? | Share of values outside the format | john.smith@gmail,com |
| Consistency | Do two systems say the same thing? | Divergence rate between CRM and email tool | Contact unsubscribed in one, active in the other |
| Timeliness | Is the data still true? | Age of the last update | Work address of an employee who left |
| Uniqueness | Does an entity appear only once? | Duplicate rate | Same person entered with two addresses |
Validity is checked against a rule, accuracy against reality, which is why an address can be valid without being accurate. marie@example.com follows the syntax and passes the signup form check. It does not exist.
Measuring data quality starts with profiling
Measuring starts with data profiling: a sweep of each table that counts empty values and duplicates, then reads the range of update dates. On a CRM export of 50,000 rows, a dozen SQL queries or a spreadsheet with a pivot table are enough for a first assessment.
Four metrics cover most of what a marketing team needs:
- the completeness rate: fields filled in divided by fields required, calculated field by field and segment by segment rather than as an average;
- the duplicate rate: redundant records divided by total records;
- the hard bounce rate per send: addresses permanently rejected divided by messages sent;
- the median age of the last update, which flags dormant segments.
Set a threshold per use and write it down (99% completeness required on email, 60% tolerated on job title, for example). Without one, an indicator at 94% tells you nothing: acceptable for an optional field, alarming for the email address in a sending list.
The order in which to tackle the criteria
Start with uniqueness and validity. These are the two criteria you can fix in bulk and without debate: deduplication and a format check can be scripted, and the result is verifiable the same day.
Completeness comes next, because an empty field only gets filled with a source or a follow-up. Accuracy and timeliness need a check against reality; they cost more per row, so they go to the segments that actually get used. Consistency comes last, since it assumes each system is already clean before you compare it with the others.
What bad data quality costs
Several million dollars a year for a large organization, according to the most quoted estimates. They are self-reported and do not transfer as is to a small business.
Gartner put the average cost of poor data quality at $12.9 million a year in 2020, a result drawn from a survey of 154 reference customers of 16 data quality software vendors. A self-reported estimate, then. Older and more spectacular, the $3 trillion a year figure for the US economy was popularized by Thomas Redman in the Harvard Business Review in 2016. No published method reproduces it; it traces back to a 2011 extrapolation later repeated by IBM, so it gives an order of magnitude and nothing more.
For a marketing team the cost shows up lower down, in lines you can count: lost sends, sales follow-ups on obsolete records, the same discount mailed twice to one customer. Run the calculation on your own data, with your own unit costs.
Email addresses as an example: bounces and deliverability
An address list ages silently. Nobody tells the marketing team when a contact changes jobs. An employee leaves, the mailbox is closed, and the address goes from valid to rejected overnight without any CRM field saying so. The first signal arrives at the next send, as an NDR (non-delivery report) returned by the receiving server with a 550 5.1.1 code, meaning the mailbox does not exist.
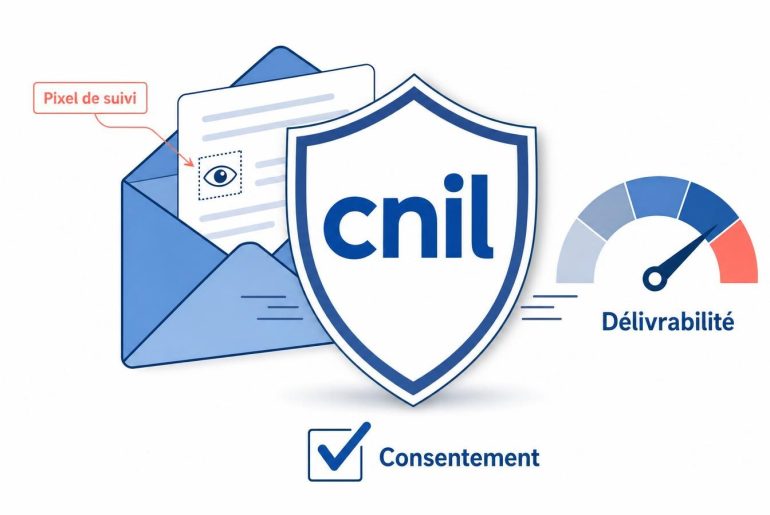
Google publishes precise thresholds, and none of them covers bounces. Its sender guidelines ask you to keep the spam rate reported in Postmaster Tools below 0.10% and never reach 0.30%; they also recommend reducing volume when messages bounce. No hard bounce threshold appears there. Each team has to set its own, knowing that a rising rate damages sender reputation and that Gmail’s filtering then hits the whole campaign, active contacts included.
Verifying addresses before sending cuts this mechanism at the source: syntax, domain existence, reachable mailbox, detection of catch-all domains and disposable addresses. Against the common objection (“we’ll filter afterwards”), the bounce has already happened by the time you see it, and it weighs on your domain’s reputation. On a real list, email verification of a sample of 1,000 to 2,000 addresses drawn from the next campaign gives a usable invalid rate before you commit the whole list. On the deliverability side, a rising bounce rate weighs on the sending domain’s reputation just as a badly configured SPF or DKIM setup does.
What the GDPR says about accuracy
Data quality is also a legal matter: Regulation (EU) 2016/679, applicable since 25 May 2018, makes it an obligation. Article 5(1)(d) requires personal data to be “accurate and, where necessary, kept up to date”, with every reasonable step taken to erase or rectify inaccurate data without delay, having regard to the purpose.
An email list that has not been cleaned in 3 years holds records of former employees, closed companies and people who changed address. The principle applies to them. Collection matters too: a double opt-in sign-up weeds out typos from the start, since the address has to answer before it is saved.
Fixing a degraded database
Fix things in the order of the table above, on a copy of the database, because a correction made in place cannot be recovered. Four operations cover most of the work:
- deduplication: group the records that point to the same person (same normalized email, same name and same company) and keep the most complete one;
- normalization: one format for dates, countries, titles and addresses, with emails in lowercase;
- enrichment: fill empty fields from a reliable source, otherwise the field stays marked as unknown;
- deletion or archiving of records with no remaining purpose, which ties in with the GDPR data minimization principle.
Each rule needs an owner, often called a data steward: the person who decides which record wins and signs off the thresholds. Without that name written down somewhere, cleanup depends on everyone’s goodwill and starts from zero at the next campaign.
Mistakes that keep coming back
Cleaning without fixing the source. A database purged in January is polluted again by March if the signup form still accepts gmail,com or test addresses. A check at entry costs less than 10 purges.
Merging two CRMs without a survival rule. When two records contradict each other, someone decides which one wins: the most recent address, the most reliable source or the most complete record. Without a written rule, the merge overwrites correct data with outdated data.
Measuring on a global average. A completeness rate of 92% across the whole database hides an “email” field filled at 99% and a “job title” field at 40%.
Mistaking the tool for the method. Data quality software applies rules; it does not choose them. Tool selection and long-term monitoring are covered on our page about Data Quality Management.